Tutorials
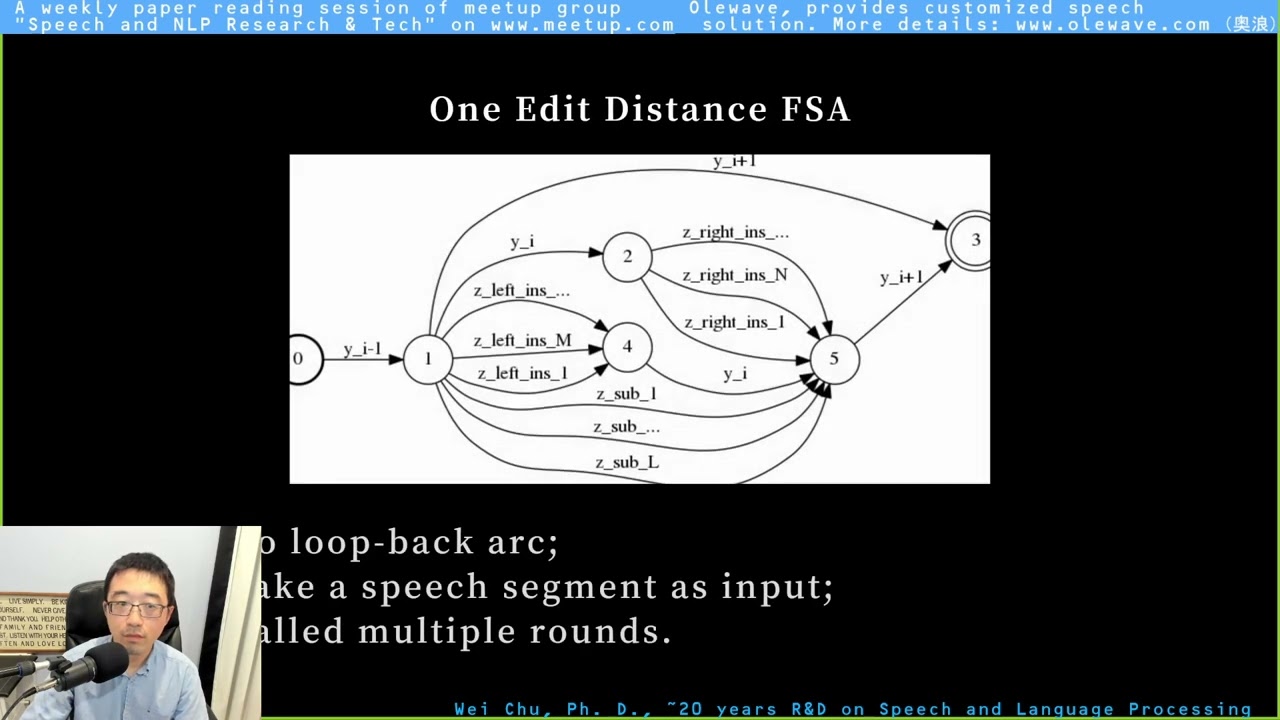
One-Edit-Distance FSA/Network-based (OEDN) in Mispronunciation Detection and Accented ASR
Non-native acoustic modeling has a chicken-and-egg problem: bad phone alignments produce bad models, and bad models produce bad alignments.

Tutorials
Olewave's most detailed illustration of RNN-T: Sequence Transduction with Recurrent Neural Networks
Alex Graves' RNN-T paper is the quiet ancestor of nearly every streaming ASR system shipping today, from Google's on-device recognizer to countless open-source…